GPT 5.5 Is The Worlds Best Coding Model
By Beau Johnson · · 16 min · 5K views
About this video
Transcript
Read the full transcript
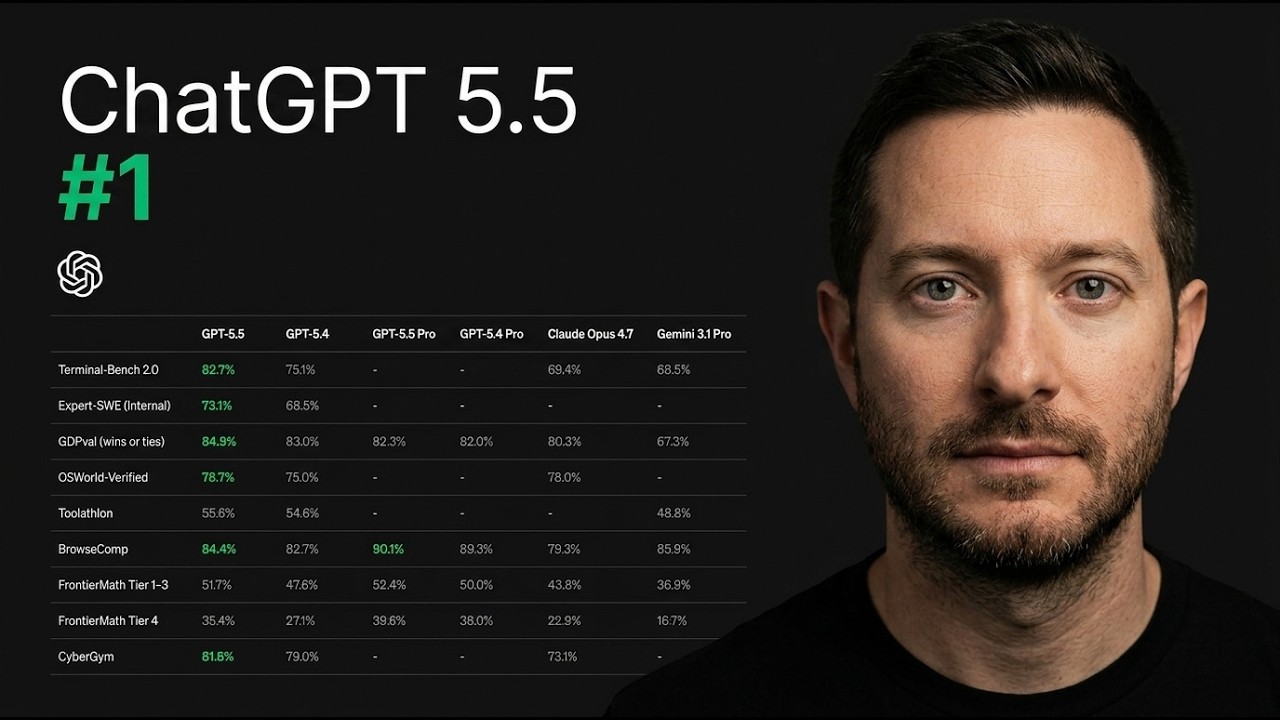
0:00GPT 5.5 just dropped about 5 minutes ago and in this video we're going to be going over all of the latest advancements and features and updates. It is the world's best AI coding model and you can see here on the benchmark score it blows Opus 4.7 out of the water. I'm going to be testing it out in my open claw seeing how it performs, but let's go over some of the updates as to why you should be using GPT 5.5 now. So you can see here on terminal bench it scored 82% compared to Opus 69.4%. You got sweet internal at 73% and as well as GDP valve with 85%.
0:45It is blowing Opus out of the water and this is crazy. You got frontier math at 35% versus 22% for Opus. So this is crazy because a lot of people have complained on how Opus 4.7 is not a major update over Opus 4.6. It costs a lot of money to run and through GPT 5.5 you can connect your open claw through your subscription and get better performance. Let me back up because the real story here, like if you're building and running agents every day, you know, the biggest story is, you know, what model are you going to use to run those agents and with all these changes that have happened these last few weeks, it's hard to even decide. You can see by those benchmark store scores there's a
1:31clear winner, obviously. You know, after sitting with the benchmarks and, you know, pricing for a few hours, I can tell you that GPT 5.5 is not just another model drop. It is a slot shift. It changes where GPT goes and where Opus stays. Literally Opus was the grand champion in the world for seven whole days and then 5.5 drops and it's the clear front front runner. So I'm going to walk through what actually happened and where I'm putting this thing inside of my open claw. So first the basics, like open AI shipped two models today, GPT 5.5 and 5.5 Pro and yes, there's a difference. Both have still the 1 million token context window. Both are rolling out in chat GPT plus pro and
2:18business and codex. Pro users get 5.5 Pro on top. The API is not live yet, but they said it's going to be very soon, which means within a week or so based on how they've done it before and it is not on open router yet. So if you are a builder waiting to wire this into your pipeline, you're going to be waiting just a few more days, but that's fine. Use this time to read the benchmarks because the benchmarks are where the interesting decisions live. So I'm going to hit you with the one and the one number that actually matters for all of us that build. Terminal bench 2.0. This is the benchmark gold standard that measures how well a model can operate a shell, run commands, recover from errors, finish a task and end to end in
3:04a real terminal. Real quick, before we keep going, if you're watching this and you want to actually build with some of these tools, not just watch videos about them, then you're going to want to check out our community down below shipping school. We have a full cloud code course, a full open claw course and four live bootcamps every single week where we actually help you get set up from scratch. Like actually set this thing up, not just watch a tutorial and figure it out by yourself. And we also provide one-on-one coaching so you can book a call with me, we can share screens and I can help you get cloud code or open claw running on your machine. That's it, no fluff. I built this community because watching YouTube's only gets you so far. We launched it just 3 days ago and we have over 55 members. You need people
3:51around you who are actually building, people who hold you accountable and coaches who can help you when you get stuck. I'll put the link in the description down below. Get in now before the price goes up. GPT 5.5 scored 82%. That's state of the art. GPT 5.4, the previous open AI flagship, got 75%. Opus 4.7, which was the reigning king for 7 days until today, got 69%. So we're talking about a 13 point gap between 5.5 and Opus on terminal work. 13 points and that's pretty big. That's not a tie, that's a landslide win and, you know, if you're running anything that shells out, anything that lives in codex, anything looks like open claw agentic terminal service, you have a new
4:36default you should probably switch to today. You know, hold on here because if I just told you GPT 5.5 beats Opus across the board, you know, I would be lying and I don't do that because there is a few things here where Opus does outperform. But the other number here is sweet bench pro. That's a pull request style coding benchmark, multi-file refactors, the kind of work where you're not just running commands, you are restructuring a code base. Opus 4.7 scored 64.3% and GPT 5.5 got a 58.6%. So that's a 5.7 point gap that Opus favors. So on the PR writing side, the serious multi-file refactor work, Opus is still the king. Nothing changed there
5:22today. I'm not ripping Opus out of my main coordination agent for open claw, but I will be playing out with playing with 5.5 for my cron jobs. You know, I'm just not done with Opus. I think it's still one of the best and I use it in my cloud code setup every single day. So that slot stays with Opus. You know, and there is also sweet bench verified, which is sort of the crowd favorite benchmark. Opus 4.7 sits at 87.6%. GPT 5.5 is somewhere around 88 to 90% based on leaked numbers. Open AI did not publish the exact favor in their table. So we are basically tied there with a slight edge to GPT 5.5 on the leaked read. Hard to tell. Oz world, which
6:07measures computer use like browser automation, clicking around on a desktop, GPT 5.5 got 78.7% and Opus got 78. So they're basically tied. So not worth switching. GDP valve, which is a knowledge work test that GPT 5.5 leads Opus by 4.6 points. Frontier math tier four, the really hard math reasoning stuff, GPT 5.5 jumped from 27.1 to 35.4 and that's a pretty big jump on reasoning. Cybergum, which is the security red team benchmark, GPT 5.5 came in at 81.8%. So here's how I'm reading the full picture here. Friend to friend, amigo to amigo. GPT 5.5 is now the answer for
6:52most terminal agents. Anything shell heavy, anything codex style, anything looks like core open claw agentic service, GPT 5.5 goes there. Opus 4.7 stays the answer for complex multi-file refactors and PR style coding. Don't swap that out. Keep Rizza on Opus, which is my agent. Keep your serious refactor work on Opus because that's 5.7% point difference on sweet bench pro and that gap is real. And for computer use, browser agents and that kind of thing, pick on the price because they're basically tied. So I'm going to talk about the money here because I know that's what you want to know. GPT 5.5 is $5 per million input tokens and $30 per million output. GPT 5.5 Pro is $30 input
7:40and $180 output. For comparison, GPT 5.4, the previous flagship, was 2.5 input and 15 output. So GPT 5.5 is literally twice as more expensive than 5.4 and that's a huge price hike. You can tell by open AI's desperation there. You know, if you're running cost sensitive agents that don't need new capability, you do not just need this lift and the shift everything to 5.5 can hold off. Like think about it. You now compare 5.5 to Opus 4.7. Opus 4.7 is $15 in $75 out. GPT 5.5 at $5 in and $30 out is roughly three times cheaper than Opus at the list price. So if you were previously running Opus in your terminal as agents
8:25because it was the best available, you can now run GPT 5.5 at a third of the cost and get a 13 point boost on terminal bench. That's the trade everyone's going to make this week. GPT 5.5 Pro at $30 in and $80 out, that's basically Opus 4.7 territory. If you were not already spending on Opus for high stakes reasoning or math, don't suddenly start spending on 5.5 Pro either. It's a niche tool for a niche slot. Here's where it gets more interesting though and this is the angle that I think most builders are going to miss if they just look at the price card. Open AI is saying this out loud that GPT 5.5 uses significantly fewer tokens to complete the same task. The
9:10codex team is saying it and on the AA coding agent index, they are calling it state of the art at half the cost. If you're struggling to keep up with content, well I'm about to save you about 40 days worth of work. I [music] built something called content machine. It's 10 AI agents that run on the open claw orchestration and they handle everything. Scripts, thumbnails, X posts, blogs, outreach, clips, [music] newsletters, all of it. So I went from 1,000 subscribers to 4,000 subscribers on YouTube in 7 days using this exact system. Every single morning I wake up and the content's already done. I spend maybe 15, 20 minutes reviewing and approving them and I move on with my day. It works for any niche, [music]
9:56fitness, finance, real estate, marketing, whatever you are building and it is 100% completely customizable to your use case. So, you get the mission control dashboard, all of the cron jobs, everything I've built over the last 40 days helping me gain more and more people to subscribe and join the community. So, you plug in your own thing and it molds it to you, it learns how you talk and it writes, [music] so it doesn't sound like AI slop. $97 one time, it's not I'll put the link down below and you'll thank me later. That's the efficiency story here because if 5.5 is twice more expensive per token than 5.4, but it uses say half the tokens to do the same work, your actual bill on a real agent might be flat or even lower than what
10:425.4 was producing. So, the raw price tag is misleading here. The real test is going to be running the same task on 5.4 and 5.5 and then comparing the final cost on your invoice, not the per token headline. I'm going to do that test this week here on Openclaw and I'm going to run a lot of the same shell automation tasks on 5.4 and then on 5.5 and then just count the total tokens it consumes and then report back to the real bill. I do use the OAuth token, so I will see if it uses any more usage versus 5.4 and 5.5. That's something that I'm going to monitor. You know, if 5.5 is really state of the art and at half the cost, that's not just a new model, that's a new default for everything terminal heavy on the channel. You know, I'm going to zoom out for a second because I know that was a lot. The timing of this
11:28drop is not an accident. OpenAI did not just wake up today and decide, "Let's ship a new model." We've seen it coming. They shipped after four straight days of Chinese frontier drops. Ling 2.6 flash, Ling 2.6 1 trillion parameter from Ant Group, Hi 3 preview from Tencent, Memo from 2.5 Pro from Xiaomi and then 4 days in a row, Chinese labs were putting out frontier work. And before that, Anthropic dropped Opus 4.7 last week on April 16th, which took number one on SweeBench verified, basically embarrassed every other frontier model for a week. OpenAI was getting pressure from both sides, Chinese open weight labs on one side and Anthropic on the other and today was their response. 7
12:13weeks after GPT-5.4, 7 days after Opus 4.7. Boom, 5.5 land, here we are. This is the rhythm of frontier AI right now. You're not going to go 2 months without a major drop anymore. The labs are trading blows every week. Opus 4.7 was state of the art for exactly 7 days, oh boy. And before you know, on Terminal Bench, that just dropped an hour ago and that's the pace we're seeing things come out. So, if you're a builder and you cannot lock into one model for a year, I would forget about it. You know, you have to route, you have to have multiple providers wired in and you have to be willing to switch slots when the benchmarks move, which is pretty cool actually because it means your stack gets better every few weeks without you having to rebuild anything. So, here is
12:59what I'm going to do on my setup this week. As you know, I run 17 AI agents within Openclaw that handles my entire businesses and content pipeline. And you can even steal this if you want, I don't care. I'm switching my terminal agent default to GPT-5.5. That means Codex style work, shell automation, anything that looks like a shell loop is going to route through GPT-5.5 the moment the API goes live. I'm keeping the Rizza, our outline and script writer on Opus 4.7 because Rizza writes long-form video scripts and Opus still crushes that style work. I'm keeping my serious multi-file coding on Opus because SweeBench Pro still favors Opus. And I'm running one experiment on GPT-5.5 Pro for hard reasoning tasks to
13:47see if it clears Opus on the stuff where Opus currently wins. If it does, 5.5 Pro starts showing up in my reasoning slot, too. I would say. So, if you're running Openclaw, this is the one-line config change for your agent once the API drops. You just point your terminal agents at GPT-5.5 and you leave your content agents on Claude 4.7 and that's it. You don't need to rebuild your stack, you just reslot. So, a quick note is that because I know a lot of people are going to ask, "Do you switch from Claude to GPT completely?" No, not at all. I have a multiple different LLMs handling different tasks within my whole system. That's the wrong question, really. The right question is which model gives you the best performance in which slot. Claude is still the best for
14:32long-form writing, long-form coding, complex multi-file file refactors, anything that needs taste and judgment. GPT-5.5 is now the best at terminal work, which is raw shell automation, command execution and likely to be the best for certain computer use and reasoning tasks as well. So, you want a combination of both in your setup. You pick up on the task, not the brand and that's the game plan. The other thing, too, is people are already asking what Anthropic is going to do. Alex Finn teased something called Mythos earlier today on X that is going to be coming out sooner rather than later, but there is no official drop yet. But the rumor mill is active. If Anthropic responds this week with a new Opus or new tier, we will cover it on the same day and that's the whole point of this channel, building in public, keeping up with the
15:18pace and so you don't get behind. So, that's the GPT-5.5 state of the art on Terminal Bench by 13 points over Opus, but still behind Opus on multi-file PR coding, three times cheaper than Opus at the list price, two times more expensive than GPT-5.4 on paper, but probably cheaper in real-world use because of the token efficiency. A new default for your terminal agents, not a replacement for your whole stack. Don't do that. So, if you want the source, I got it linked down below for the OpenAI announcement and if you want to see how I'm actually routing this stuff across Openclaw day-to-day, we are doing this inside of our community that I launched 31 days ago. We got 214 members and we do nine live boot camp calls every single week. We're even having a local call this Sunday where it's how to install local LLMs on your machine. So, if you got the
16:05hardware, you will learn how to install a local model to run your whole Openclaw workflow. So, like I said, I'll put the link to that down below and if you haven't subscribed already, please do because I release about four videos every single day covering AI news. We'll see in the next one. Be blessed.
Build this with us, live
Shipping Skool is a free community with 4 live build sessions a week. Bring your idea.
Join Shipping Skool — Free